LLM Benchmark Scores 2026: AI Model Benchmark Statistics for ChatGPT, Gemini, and Claude
Published November 21, 2026
ChatGPT, Gemini, and Claude run on families of models that OpenAI, Google, and Anthropic replace every few weeks, and each new model arrives with test scores its maker picked and ran. Independent groups rerun many of those tests on every model, so we used their results to see which company's models lead in late 2026 and how often the lead has changed hands.
Our analysts downloaded Epoch AI's benchmark database on November 21, 2026 and built a ledger of 553 scores for OpenAI, Google, and Anthropic models released in 2026 on eight public benchmarks and on Epoch's combined capabilities index, which covers 39 of those models. We dated each new top score from the release date of the model that set it, compared each lab's best result at the start of the year with its best result now, and added four public leaderboards as they stood on November 20 and 21.
Key Findings
- Claude Fable 5.2, released November 9, 2026, has the highest Epoch Capabilities Index score of any model at 173.4. OpenAI's GPT-6.2 Astra, released eight days later, scores 172.8, and Epoch's uncertainty ranges for the two models overlap almost completely.
- OpenAI models held the top capability score on 226 of the 325 days from January 1 to November 21, 2026, and Anthropic models held it on 99. No Google model held it this year.
- Anthropic's best score rose 21.5 points in 2026, the largest gain of the three labs. OpenAI released the most models with an index score, 15, against 12 each for Google and Anthropic.
- The best ARC-AGI-2 score from the three labs rose from 54.2% to 95.8% this year, and five other benchmarks in our panel now have top scores of 94% or higher.
- On Text Arena, where people vote for the chat answer they prefer, Google's Gemini 4 Carbon was rated first at 1,527 on November 20, 2026, and no OpenAI model ranked in the top 15.
In the following sections, we compare each lab's best model on eight benchmarks, every change in the top capability score since January, how many models each lab released, how far top scores rose this year, how often the newest models get basic facts right, where they rank on public leaderboards, and what each top model costs to run.
LLM Benchmark Scores by Lab, November 2026
This table shows the best score any OpenAI, Google, or Anthropic model has posted on Epoch's combined index and on seven individual benchmarks, as of November 21, 2026. Each cell lists the model that set the score.
| Benchmark | What it tests | Best OpenAI model | Best Google model | Best Anthropic model | Top lab |
|---|---|---|---|---|---|
| Epoch Capabilities Index | Combined score from more than 50 benchmarks | GPT-6.2 Astra, 172.8 | Gemini 4 Carbon, 169.7 | Claude Fable 5.2, 173.4 | Anthropic |
| GPQA Diamond | Graduate-level science questions | GPT-6.2 Astra, 96.8% | Gemini 4 Hydrogen, 96.8% | Claude Fable 5.2, 96.0% | Tie: OpenAI and Google |
| Humanity's Last Exam | Expert questions across many fields | GPT-6 Astra, 54.8% | Gemini 3.1 Pro Preview, 46.4% | Claude Fable 5.1, 46.5% | OpenAI |
| FrontierMath Tiers 1-3 | Research-level math problems | GPT-6 Astra, 93.7% | Gemini 4 Neon, 91.2% | Claude Fable 5.2, 95.1% | Anthropic |
| ARC-AGI-2 | Abstract visual puzzles | GPT-6.2 Astra, 95.8% | Gemini 4 Carbon, 94.2% | Claude Fable 5.2, 93.8% | OpenAI |
| SimpleQA Verified | Short factual questions | GPT-6.2 Astra, 78.5% | Gemini 4 Carbon, 77.7% | Claude Fable 5.2, 94.0% | Anthropic |
| SimpleBench | Everyday reasoning and trick questions | GPT-6 Astra, 86.5% | Gemini 4 Neon, 94.4% | Claude Fable 5.2, 94.9% | Anthropic |
| Chess Puzzles | Chess puzzles | GPT-6.2 Astra, 78.0% | Gemini 4 Neon, 83.0% | Claude Fable 5.2, 79.0% |
Key Findings
- Anthropic holds the top score on four of the eight measures, OpenAI on two, and Google on one, Chess Puzzles. OpenAI's GPT-6.2 Astra and Google's Gemini 4 Hydrogen tie on GPQA Diamond at 96.8%.
- On GPQA Diamond, the best models from all three labs score within 0.8 points of each other, less than two questions apart on the 198-question test. The widest gap between the top two labs in the table is on SimpleQA Verified, where Claude Fable 5.2 leads GPT-6.2 Astra by 15.5 points.
- Google's best Humanity's Last Exam result on file, 46.4%, comes from Gemini 3.1 Pro Preview in February. The three Gemini 4 models with index scores, released from October 13 to November 12, had no score on that test in Epoch's records as of November 21.
Every Change in the Top Capability Score Since January 2026
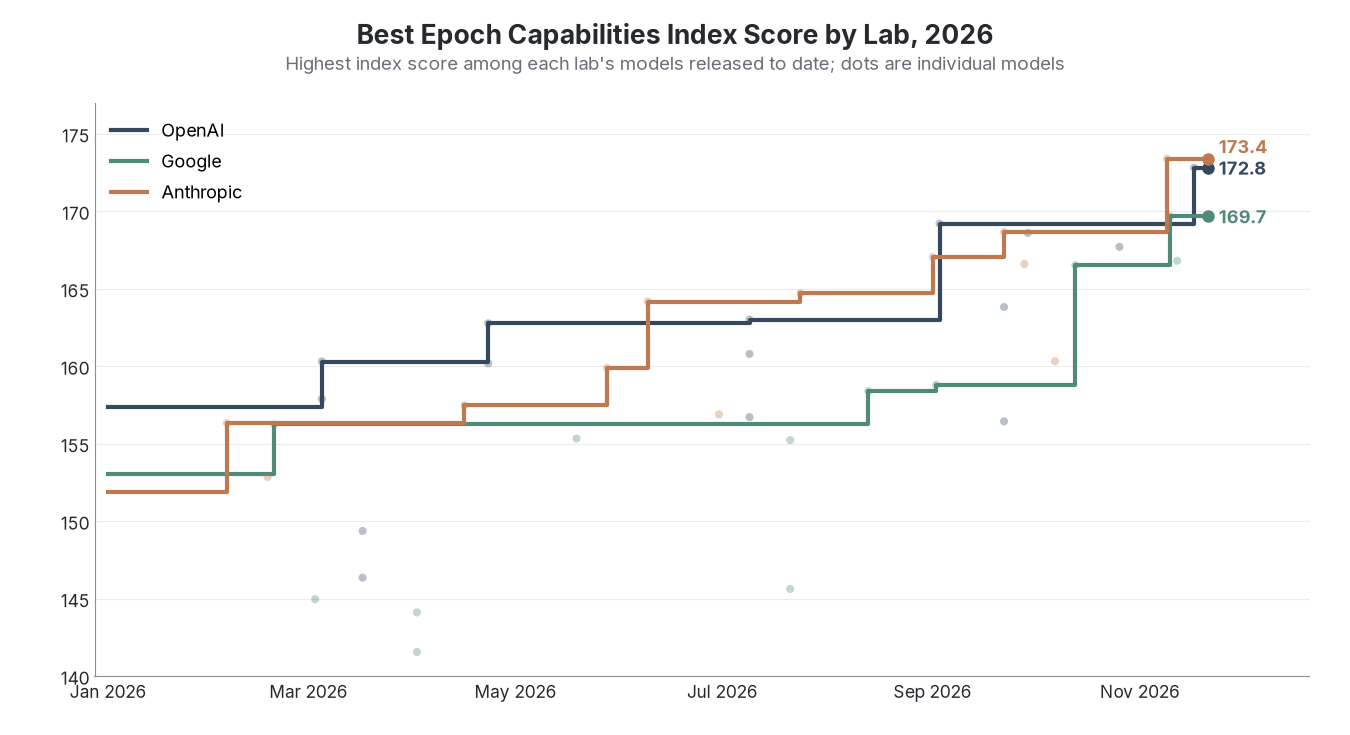
Epoch's capabilities index combines results from many benchmarks into one scale, which makes it the steadiest single measure of which lab's model led at any point in the year. We dated each new record from the release date of the model that set it.
| Release date | Model | Lab | Index score | Gain over previous top |
|---|---|---|---|---|
| Dec. 11, 2025 (top score on Jan. 1) | GPT-5.2 Pro | OpenAI | 157.4 | - |
| March 5, 2026 | GPT-5.4 Pro | OpenAI | 160.3 | +2.9 |
| April 23, 2026 | GPT-5.5 Pro | OpenAI | 162.8 | +2.5 |
| June 9, 2026 | Claude Fable 5 | Anthropic | 164.2 | +1.4 |
| July 24, 2026 | Claude Opus 5 | Anthropic | 164.7 | +0.5 |
| Sept. 1, 2026 | Claude Fable 5.1 | Anthropic | 167.1 | +2.4 |
| Sept. 3, 2026 | GPT-6 Astra | OpenAI | 169.2 | +2.1 |
| Nov. 9, 2026 | Claude Fable 5.2 | Anthropic | 173.4 | +4.2 |
Key Findings
- The top score changed hands between labs three times. Anthropic took it on June 9 with Claude Fable 5, OpenAI took it back on September 3 with GPT-6 Astra two days after Claude Fable 5.1 set a new mark, and Anthropic retook it on November 9 with Claude Fable 5.2.
- Claude Fable 5.2's 4.2-point gain over GPT-6 Astra is the largest single jump in the record this year. Eight days later, GPT-6.2 Astra came within 0.6 points of it.
- Google's best model, Gemini 4 Carbon at 169.7, ranks third among the labs, 3.7 points behind the leader. Gemini 4 Carbon was released on November 10, the day after Claude Fable 5.2.
Models Released and Capability Gained by Each Lab in 2026
The three labs released 39 models in 2026 with enough benchmark results for Epoch to give them an index score. This table compares how many each lab released and how far its best score moved between January 1 and November 21.
| Lab | Models with an index score released in 2026 | Best score on Jan. 1, 2026 | Best score on Nov. 21, 2026 | Change |
|---|---|---|---|---|
| Anthropic | 12 | 151.9 (Claude Opus 4.5) | 173.4 (Claude Fable 5.2) | +21.5 |
| 12 | 153.0 (Gemini 3 Pro) | 169.7 (Gemini 4 Carbon) | +16.7 | |
| OpenAI | 15 | 157.4 (GPT-5.2 Pro) | 172.8 (GPT-6.2 Astra) | +15.4 |
Key Findings
- Anthropic started 2026 in third place, 5.5 points behind OpenAI, with Claude Opus 4.5 as its best model. It released 12 scored models this year, from Claude Opus 4.6 in February to Claude Fable 5.2 in November.
- Google's 12 scored models include two open-weight Gemma 4 models released on April 2, so 10 of the 12 are Gemini models.
- Six of OpenAI's 15 scored models belong to the GPT-6 family, which began with GPT-6 Astra on September 3. Each new GPT-6 release has scored at least 156.4.
How Far Top Benchmark Scores Rose in 2026
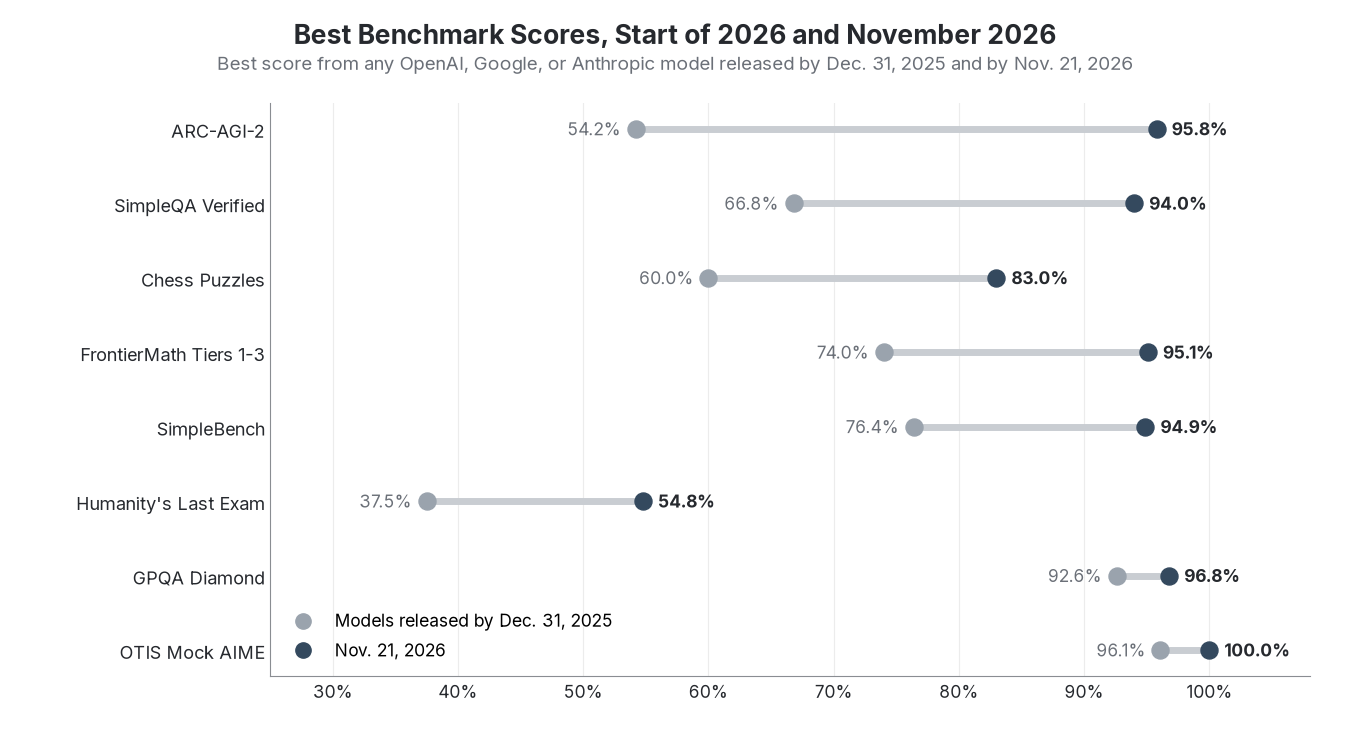
For each benchmark, we compared the best score from any OpenAI, Google, or Anthropic model released by December 31, 2025 with the best score from any of their models as of November 21, 2026.
| Benchmark | Best score, models released by Dec. 31, 2025 | Best score, Nov. 21, 2026 | Change |
|---|---|---|---|
| ARC-AGI-2 | 54.2% (GPT-5.2 Pro) | 95.8% (GPT-6.2 Astra) | +41.6 points |
| SimpleQA Verified | 66.8% (Gemini 3 Flash Preview) | 94.0% (Claude Fable 5.2) | +27.2 points |
| Chess Puzzles | 60.0% (GPT-5.2 Pro) | 83.0% (Gemini 4 Neon) | +23.0 points |
| FrontierMath Tiers 1-3 | 74.0% (GPT-5.2 Pro) | 95.1% (Claude Fable 5.2) | +21.1 points |
| SimpleBench | 76.4% (Gemini 3 Pro Preview) | 94.9% (Claude Fable 5.2) | +18.5 points |
| Humanity's Last Exam | 37.5% (Gemini 3 Pro Preview) | 54.8% (GPT-6 Astra) | +17.3 points |
| GPQA Diamond | 92.6% (Gemini 3 Pro Preview) | 96.8% (GPT-6.2 Astra) | +4.2 points |
| OTIS Mock AIME | 96.1% (GPT-5.2) | 100.0% (models from all three labs) | +3.9 points |
Key Findings
- ARC-AGI-2, a set of abstract visual puzzles built to be easy for people and hard for AI, gained 41.6 points, the most of any benchmark in our panel. GPT-6.2 Astra's 95.8% is the highest ARC-AGI-2 score in Epoch's records.
- GPQA Diamond and the OTIS Mock AIME math exam started 2026 with top scores above 92%, and models from all three labs now score 100% on the AIME set, so neither test separates the leading models any longer.
- Stanford's 2026 AI Index found that frontier models gained 30 percentage points on Humanity's Last Exam in a single year and that tests built to stay hard for years are being saturated in months. The best score on that exam in our data rose another 17.3 points in 2026, to 54.8%.
Coding results are harder to follow across the whole year. Epoch's own SWE-bench Verified runs, which ask a model to fix real issues from open-source Python projects, stop at models released in May 2026. In those runs, Claude Opus 4.7 solved 83.5% of the issues, a pre-release version of GPT-5.5 solved 80.6%, and Gemini 3.5 Flash solved 79.3%.
Factual Accuracy Scores on SimpleQA Verified
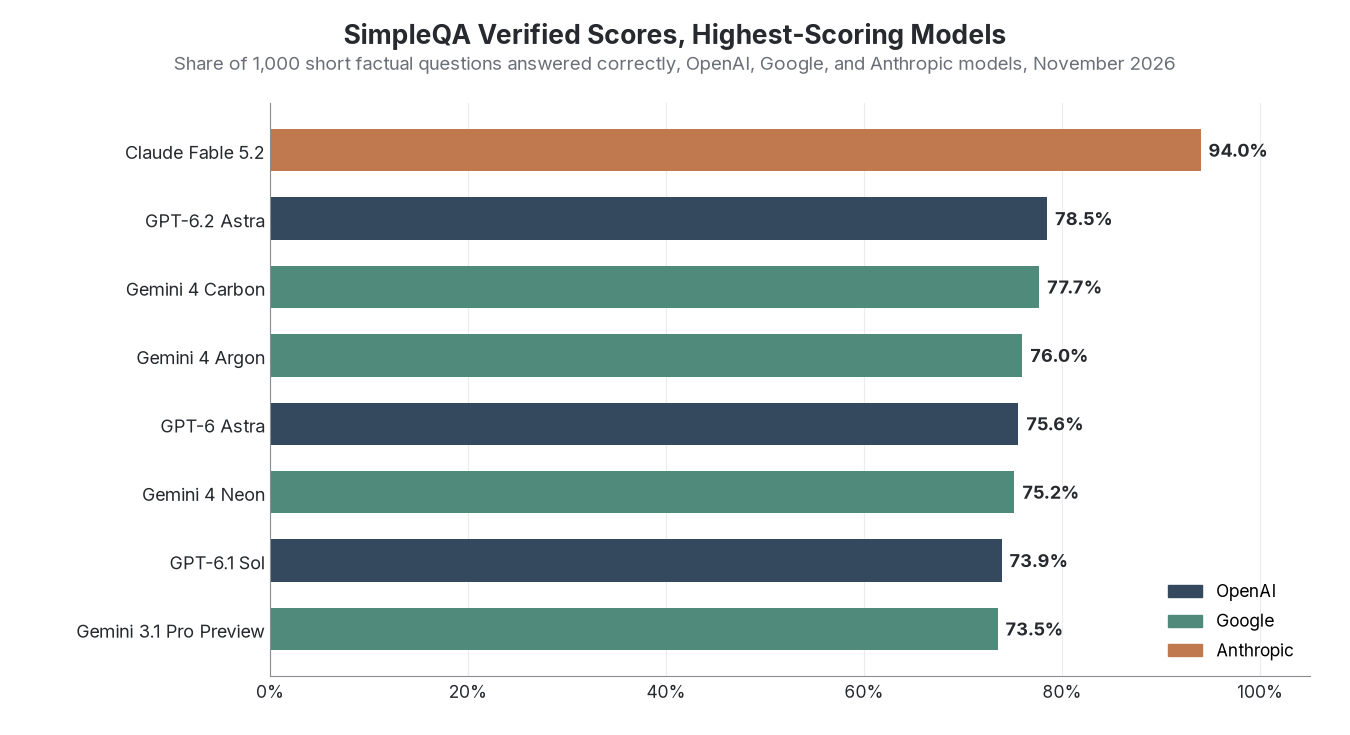
SimpleQA Verified asks 1,000 short factual questions about people, places, dates, and numbers, and Epoch reports the share each model answers correctly. It measures what a model knows on its own, which is the closest public test of how ChatGPT, Gemini, or Claude handles a fact question when it does not search the web.
| Model | Lab | Released | Share of 1,000 questions answered correctly |
|---|---|---|---|
| Claude Fable 5.2 | Anthropic | Nov. 9, 2026 | 94.0% |
| GPT-6.2 Astra | OpenAI | Nov. 17, 2026 | 78.5% |
| Gemini 4 Carbon | Nov. 10, 2026 | 77.7% | |
| Gemini 4 Argon | Oct. 13, 2026 | 76.0% | |
| GPT-6 Astra | OpenAI | Sept. 3, 2026 | 75.6% |
| Gemini 4 Neon | Nov. 18, 2026 | 75.2% | |
| GPT-6.1 Sol | OpenAI | Sept. 29, 2026 | 73.9% |
| Gemini 3.1 Pro Preview | Feb. 19, 2026 | 73.5% |
Key Findings
- Claude Fable 5.2 answered 94.0% correctly, 23.2 points more than Claude Fable 5.1 scored when it was released in September and 15.5 points more than the next model, GPT-6.2 Astra.
- Smaller models know far fewer facts. Claude Haiku 5.5, Anthropic's smallest current model, answered 23.8% correctly.
- Epoch changed the test on August 27, 2026 to ask every model for a best guess, because refusal rates had varied widely. Asked the bare question, Claude Haiku 4.5 declined to answer 82% of the questions, against 2% for Gemini 3.1 Pro.
Text Arena, Agent Arena, and Intelligence Index Standings
Leaderboards built on human votes and on longer agent tasks rank the same models differently from single tests. This table lists each lab's highest-ranked model on four public leaderboards on November 20 and 21, 2026.
| Leaderboard | What it measures | Top OpenAI model | Top Google model | Top Anthropic model |
|---|---|---|---|---|
| Text Arena (Nov. 20) | Human votes between two chat answers | Not in the top 15 | Gemini 4 Carbon, 1,527 (#1) | Claude Opus 5.5, 1,506 (#5) |
| Agent Arena Index (Nov. 21) | Ratings on multistep agent tasks | GPT-6.2 Astra, 1,291 (#6) | Gemini 4 Neon, 1,333 (#3) | Claude Fable 5.2, 1,448 (#1) |
| Artificial Analysis Intelligence Index (Nov. 21) | Composite of evaluations run by Artificial Analysis | GPT-6.2 Astra, 62 | Gemini 4 Neon, 61 | Claude Fable 5.2, 65 |
| Epoch Capabilities Index (Nov. 21) | Combined score from more than 50 benchmarks | GPT-6.2 Astra, 172.8 | Gemini 4 Carbon, 169.7 | Claude Fable 5.2, 173.4 |
Key Findings
- Text Arena ranked 426 models on 9,213,799 votes as of November 20. Google models hold the top three places, Gemini 4 Carbon leads Gemini 4 Argon by 7 points, and Claude models hold six of the next seven places.
- Stanford's 2026 AI Index put the top Arena ratings in March 2026 at 1,503 for Anthropic, 1,494 for Google, and 1,481 for OpenAI. By November 20, Google had moved from second to first of the three labs, and Gemini 4 Carbon's 1,527 was 33 points above Google's March figure.
- Claude Fable 5.2 leads Arena's agent index by 112 points over second place. On Arena's separate rating of whether an agent follows the user's intent and reports its work honestly, OpenAI models hold the top three places, led by GPT-6.2 Sol at 85.2.
What It Costs to Run the Top Models
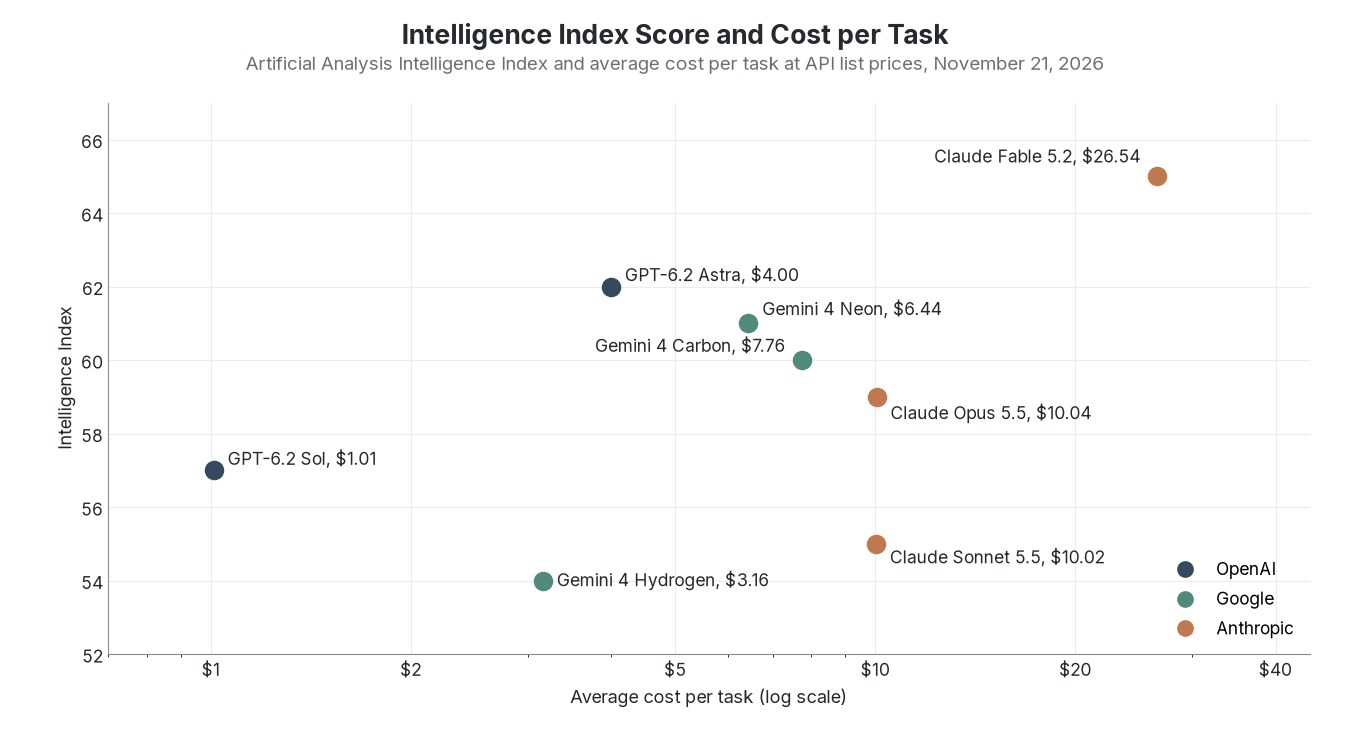
Artificial Analysis runs each model through the tasks in its Intelligence Index and publishes the average cost and time per task at API list prices. This table lists the eight highest-scoring OpenAI, Google, and Anthropic models on November 21, 2026, at the reasoning setting Artificial Analysis lists for each.
| Model | Lab | Reasoning setting | Intelligence Index | Cost per task | Minutes per task |
|---|---|---|---|---|---|
| Claude Fable 5.2 | Anthropic | Max | 65 | $26.54 | 42.2 |
| GPT-6.2 Astra | OpenAI | Max | 62 | $4.00 | 14.2 |
| Gemini 4 Neon | Xhigh | 61 | $6.44 | 22.3 | |
| Gemini 4 Carbon | High | 60 | $7.76 | 36.6 | |
| Claude Opus 5.5 | Anthropic | Max | 59 | $10.04 | 25.6 |
| GPT-6.2 Sol | OpenAI | Max | 57 | $1.01 | 9.7 |
| Claude Sonnet 5.5 | Anthropic | Max | 55 | $10.02 | 32.4 |
| Gemini 4 Hydrogen | Xhigh | 54 | $3.16 | 15.9 |
Key Findings
- Claude Fable 5.2 scored 3 points higher than GPT-6.2 Astra but cost $26.54 per task, 6.6 times GPT-6.2 Astra's $4.00, and took 42.2 minutes per task against 14.2.
- GPT-6.2 Sol scored 57 for $1.01 a task, the lowest cost of the eight. At these rates, 1,000 tasks cost about $1,010 on GPT-6.2 Sol and $26,540 on Claude Fable 5.2.
- Google's two highest-scoring models, Gemini 4 Neon and Gemini 4 Carbon, cost $6.44 and $7.76 a task, both less than any of the three Anthropic models in the table.
What the 2026 Benchmark Scores Mean for AI Search
The models behind ChatGPT, Gemini, and Claude now score within a few points of each other on most reasoning and math tests, and a new release from any of the three labs can reorder the standings within days. The clearest differences left between the top models are in factual recall, cost, and the kinds of answers people prefer in head-to-head votes.
For companies that track how AI assistants describe them, factual recall is the measure closest to that concern. SimpleQA Verified does not test brand facts, but its top scores range from 73.5% to 94.0% among the eight best models from the three labs, a wider spread than on any other benchmark in our panel.
Benchmarks are wearing out quickly. Six of the eight tests in our panel have top scores of 94% or higher, and Stanford's AI Index found invalid-question rates as high as 42% on GSM8K, a widely used math test. Epoch built its capabilities index for this problem: it combines more than 50 benchmarks so models can still be compared after single tests reach their ceiling.
GPT-6.2 Astra, released on November 17, is the newest model in our ledger, and its 95.8% on ARC-AGI-2 is the highest score any model has posted on that test in Epoch's records.
Data: llm-benchmark-scores-2026.csv
Data Collection and Methodology
Source 1 is our own research, compiled on November 21, 2026: a ledger of 553 benchmark and index scores for OpenAI, Google, and Anthropic models released in 2026, a dated record of every new top score on the Epoch Capabilities Index, a count of scored releases by lab, and a comparison of best scores at the start of the year and in November.
Scores come from Epoch AI's Benchmarking Hub data, downloaded on November 21, 2026 and used under its Creative Commons Attribution license. Epoch runs GPQA Diamond, FrontierMath, SimpleQA Verified, OTIS Mock AIME, Chess Puzzles, and SWE-bench Verified itself, and it collects Humanity's Last Exam, ARC-AGI-2, and SimpleBench results from benchmark developers and their leaderboards. Google covers models Epoch attributes to Google and Google DeepMind.
A lab's best score is the highest result from any of its models at any reasoning setting Epoch recorded. Dates are model release dates as Epoch records them. Start-of-year figures use models released on or before December 31, 2025. For the lead record, we took the highest index score among models released on or before each day from January 1 to November 21, 2026, a span of 325 days. Epoch refits its index as new results arrive, so we used the scores in its November 21 file for every model, including earlier releases.
Percentages are rounded once to one decimal place from Epoch's raw values, and changes are computed from the rounded figures shown. Text Arena ratings are from Arena's text leaderboard update of November 20, 2026. Agent Arena, honesty ratings, and Artificial Analysis figures were read from each site on November 21, 2026. Stanford AI Index figures are reported as published.
Sources
- Top GEO Agencies, LLM benchmark score ledger for OpenAI, Google, and Anthropic models released in 2026, with lead record and start-of-year comparison (Source 1, our research), compiled Nov. 21, 2026. Download the data
- Epoch AI, Capabilities and benchmarking data (benchmark_data.zip), downloaded Nov. 21, 2026. epoch.ai
- Epoch AI, Epoch Capabilities Index, updated Nov. 21, 2026. epoch.ai
- Epoch AI, SimpleQA Verified benchmark page and changelog, accessed Nov. 21, 2026. epoch.ai
- Arena, Text Arena leaderboard, updated Nov. 20, 2026. arena.ai
- Arena, Leaderboard overview, Agent Arena Index and alignment ratings, accessed Nov. 21, 2026. arena.ai
- Artificial Analysis, LLM Leaderboard, accessed Nov. 21, 2026. artificialanalysis.ai
- Stanford HAI, The 2026 AI Index Report, Technical Performance chapter, 2026. hai.stanford.edu
- SWE-bench, SWE-bench Verified leaderboard, accessed Nov. 21, 2026. swebench.com
Source: Epoch AI Benchmarking Hub data, downloaded Nov. 21, 2026; best score per lab compiled by Top GEO Agencies.
Source: Epoch AI, Epoch Capabilities Index scores, updated Nov. 21, 2026; record dates compiled by Top GEO Agencies.
Source: Epoch AI, Epoch Capabilities Index scores, updated Nov. 21, 2026; counts and changes compiled by Top GEO Agencies.
Source: Epoch AI Benchmarking Hub data, downloaded Nov. 21, 2026; comparison by Top GEO Agencies.
Source: Epoch AI, SimpleQA Verified results, downloaded Nov. 21, 2026.
Source: Arena Text leaderboard, updated Nov. 20, 2026; Arena leaderboard overview and Artificial Analysis LLM Leaderboard, read Nov. 21, 2026; Epoch AI.
Source: Artificial Analysis LLM Leaderboard, read Nov. 21, 2026.